1. VPC-Isolated Enterprise Generative AI Architectures
Moving generative AI from prototype scripts into enterprise production requires strict data security boundaries, zero data retention policies, and high-availability LLM routing. Varcio Generative AI Engineering builds production AI systems for Fortune 500 clients across three foundational platforms:
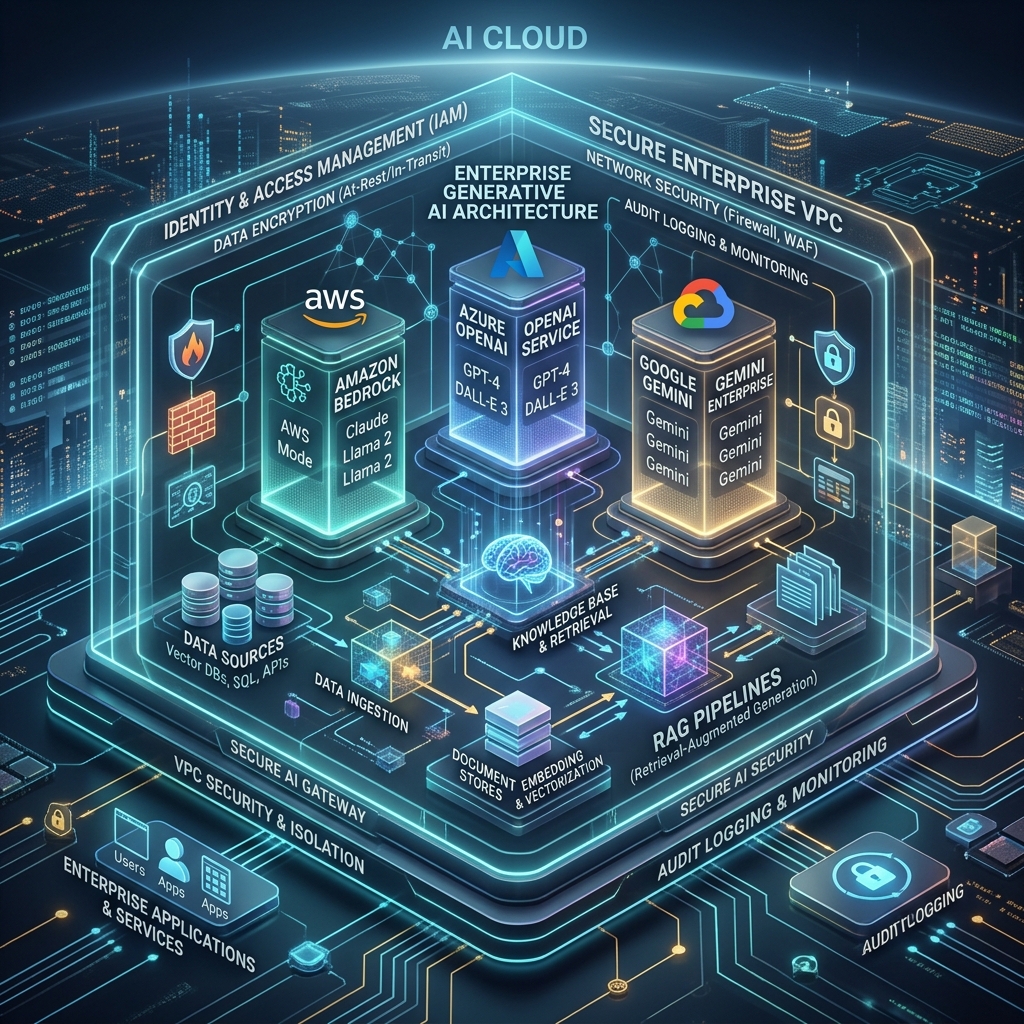
VPC PrivateLink endpoints running Claude 3.5 Sonnet, Knowledge Bases for Bedrock, and Provisioned Throughput cost optimization.
Enterprise GPT-4o deployments with Azure AI Search, hybrid vector RAG pipelines, and strict Azure RBAC controls.
Native 2M token multimodal context ingestion on Vertex AI, BigQuery Omni vector search, and fine-tuning pipelines.
2. Semantic Prompt Caching & MLOps Pipelines
Varcio integrates Redis-backed semantic prompt caching layers that intercept incoming LLM queries. By serving cached embeddings for repeated user queries, Varcio cuts LLM API costs by up to 60% while dropping P99 latencies below 40ms.